INTELLIGENCE_FEED:
SYSTEM ARCHITECTURES & ENTERPRISE BUILDS
Explore verified custom enthusiast PC rigs alongside dedicated enterprise AI server systems with calibrated thermals, multi-GPU interconnects, and real-world training benchmarks.
AI SERVER & ENTERPRISE ACCELERATOR CLUSTERS
Turnkey single-piece multi-accelerator nodes (8x NVIDIA HGX / AMD OAM) engineered for frontier LLM pre-training, massive MoE scaling, and high-throughput deep learning.
Enterprise Hardware: Turnkey systems; not modular consumer PC components in PC Builder.
8U Rackmount
💧 Direct-to-Chip Liquid
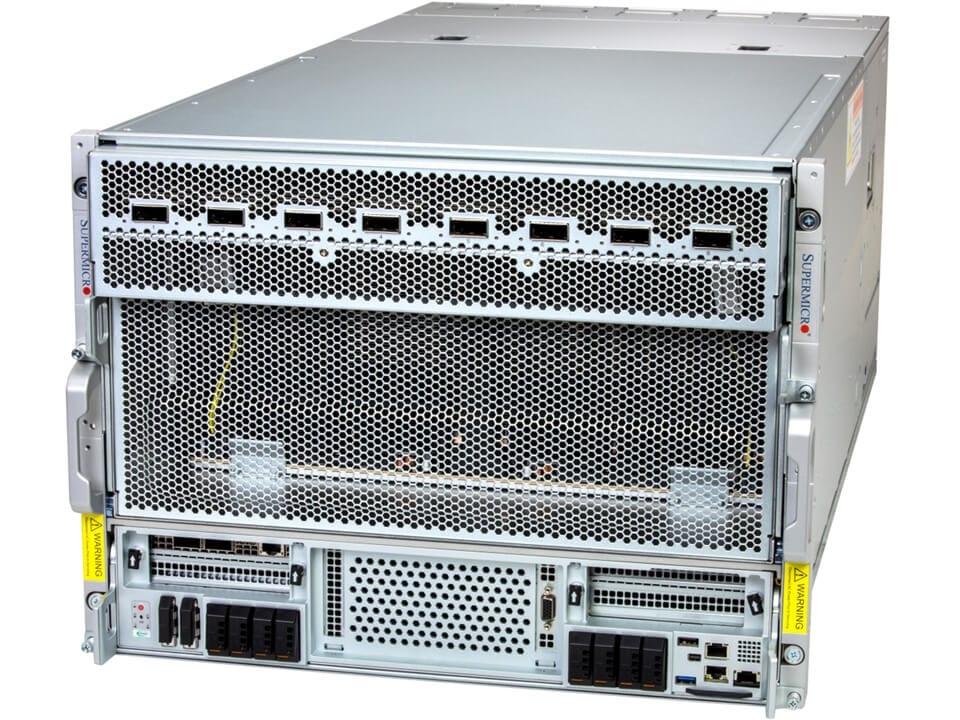
Integrated Enterprise Node
SupermicroAgile 250 kW Liquid Cooled
Supermicro Gold Series AS-8126GS 8U GPU Server
Known for agile delivery and advanced liquid-cooling systems supporting up to 250 kW rack-level thermal dissipation.
Accelerators
8x NVIDIA H200
SXM5 Baseboard
Total HBM
1,128 GB
38.4 BW
FP8 Compute
32 PFLOPS
FP8 (Sparse)
REAL-LIFE AI TRAININGPre-Training
Meta Llama 3.1 405B Base: Deploys in liquid-cooled multi-rack pods to pre-train trillion-token corpora without thermal throttling under continuous 700W GPU power load.
Throughput:~4,600 tokens/sec per 8-GPU node (FP8 Transformer Engine)
Host CPUs:Dual 5th Gen Intel Xeon Platinum 8592+ / Dual AMD EPYC 9004
System RAM:Up to 4TB DDR5-5600 ECC RDIMMs
GPU Fabric:NVIDIA NVLink 4 (900 GB/s bidirectional per GPU)
Cooling & Power:Direct-to-Chip Liquid • 10.2 kW peak chassis power
Architecture Type
Turnkey Enterprise Node
6U Rackmount
💨 High-Capacity Air
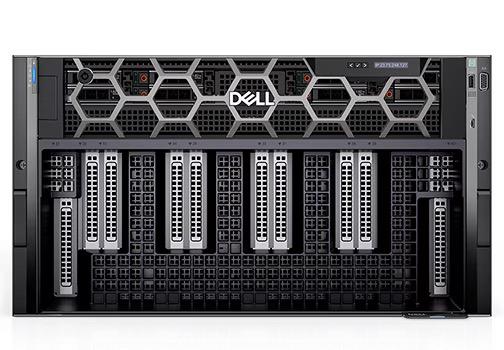
Integrated Enterprise Node
Dell TechnologiesEnterprise 8-Way AI Flagship
Dell PowerEdge XE9680 Enterprise AI Node
Features Dell's broad product ecosystem and the industry-benchmark Dell PowerEdge XE9680 8-way GPU enterprise computing platform.
Accelerators
8x NVIDIA H100
SXM5 Baseboard
Total HBM
640 GB
26.8 BW
FP8 Compute
32 PFLOPS
FP8 (Sparse)
REAL-LIFE AI TRAININGFine-Tuning
Mistral Large 2 (123B): Employed by Fortune 500 banks to fine-tune regulatory compliance LLMs using distributed Megatron-LM across internal high-security networks.
Throughput:~2,800 tokens/sec across FP8 mixed precision
Host CPUs:Dual 5th Gen Intel Xeon Scalable Processors
System RAM:Up to 4TB DDR5-5600 MT/s ECC Registered
GPU Fabric:Full-mesh NVLink 4 / NVSwitch (900 GB/s bidirectional per GPU)
Cooling & Power:High-Capacity Air • 10.0 kW maximum configuration power
Architecture Type
Turnkey Enterprise Node
8U Cray Architecture
💧 Immersion / DLC
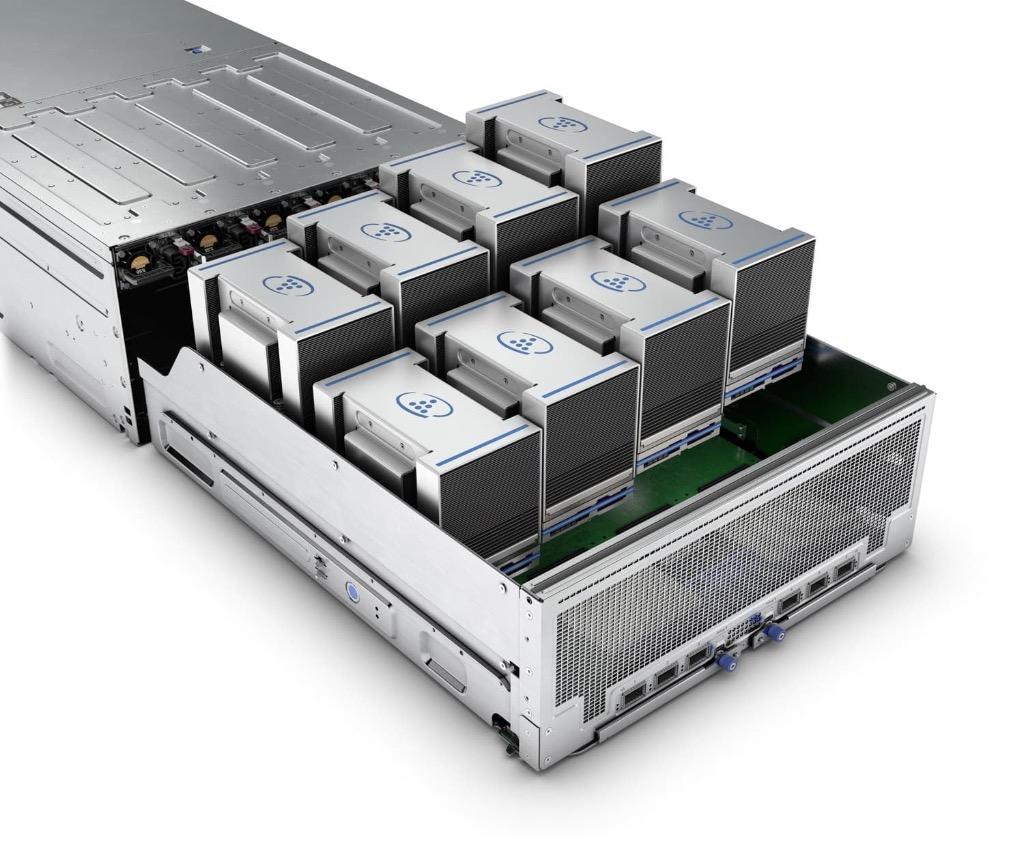
Integrated Enterprise Node
Hewlett Packard Enterprise (HPE)Exascale Cray Architecture
HPE Cray Supercomputing & ProLiant AI Node (XD670)
Offers Cray supercomputing heritage and ProLiant AI server systems with high-capacity cooling for exascale-class workloads.
Accelerators
8x NVIDIA H200
SXM5 Baseboard
Total HBM
1,128 GB
38.4 BW
FP8 Compute
32 PFLOPS
FP8 (Sparse)
REAL-LIFE AI TRAININGMoE Scaling
DeepSeek-V3 (671B Total / 37B Activated): Scales across hundreds of Cray nodes using HPE Slingshot fabric, maintaining <1.4μs latency during intense all-to-all expert routing.
Throughput:Over 14,000 tokens/sec across multi-node pod
Host CPUs:Dual 5th Gen Intel Xeon Scalable or Dual AMD EPYC 9004 Series Processors
System RAM:Up to 4TB DDR5-5600 ECC Registered
GPU Fabric:HPE Slingshot 11 / NVLink 4 (900 GB/s bidirectional per GPU)
Cooling & Power:Immersion / DLC • 10.8 kW peak system draw
Architecture Type
Turnkey Enterprise Node
6U Modular Rackmount
💧 Hybrid Liquid/Air
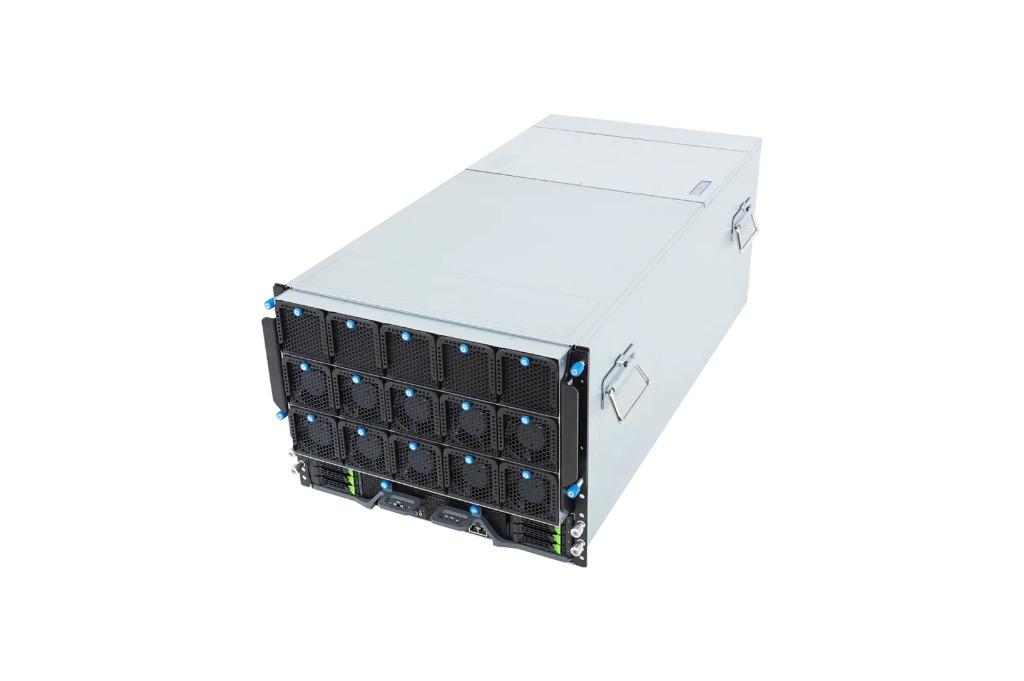
Integrated Enterprise Node
Lenovo1,128 GB High-Memory HGX
Lenovo ThinkSystem SR675 V3 / HGX H200
Provides vertically integrated supply chains and ultra-high-memory configurations like the Lenovo HGX H200 with Neptune cooling.
Accelerators
8x NVIDIA H200
SXM5 Baseboard
Total HBM
1,128 GB
38.4 BW
FP8 Compute
32 PFLOPS
FP8 (Sparse)
REAL-LIFE AI TRAININGFine-Tuning
Meta Llama 3.1 405B: With 1,128 GB HBM3e, the full FP8 weights of Llama 3.1 405B fit entirely into a single node's VRAM without network tensor sharding.
Throughput:Zero inter-node latency overhead for parameter updates
Host CPUs:Dual 4th/5th Gen AMD EPYC 9004 Processors
System RAM:Up to 3TB DDR5-4800 / 5600 MT/s ECC Registered
GPU Fabric:NVIDIA NVLink 4 (900 GB/s bidirectional per GPU, 7.2 TB/s aggregate)
Cooling & Power:Hybrid Liquid/Air • 9.8 kW max system power
Architecture Type
Turnkey Enterprise Node
8U Integrated Rack Architecture
💨 High-Capacity Air
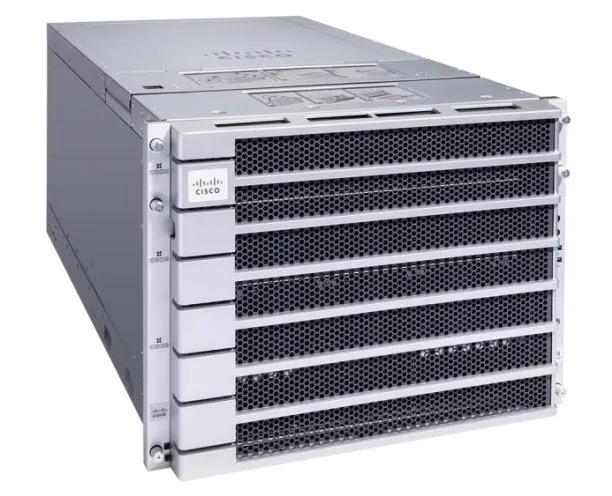
Integrated Enterprise Node
CiscoSilicon One Network Integrated
Cisco UCS C885a M8 8U Enterprise Server
Focuses on strong networking integration paired with dense hardware, backed by Cisco Silicon One and Nexus 9000 switching.
Accelerators
8x NVIDIA H100
SXM5 Baseboard
Total HBM
640 GB
26.8 BW
FP8 Compute
32 PFLOPS
FP8 (Sparse)
REAL-LIFE AI TRAININGPre-Training
Llama 3.1 70B Base (Multi-Rack Cluster): Leverages Cisco Silicon One telemetry to eliminate micro-burst congestion and PFC (Priority Flow Control) deadlock during NCCL AllReduce collectives.
Throughput:98.2% sustained network wire-speed saturation
Host CPUs:Dual Intel Xeon Platinum 8500 or Dual AMD EPYC 9004 Series Processors
System RAM:Up to 4TB DDR5 ECC Registered
GPU Fabric:900 GB/s NVLink 4 + Cisco Silicon One G200 51.2T spine-leaf Ethernet fabric
Cooling & Power:High-Capacity Air • 10.1 kW peak draw
Architecture Type
Turnkey Enterprise Node
8U Reference Architecture
💨 High-Capacity Air
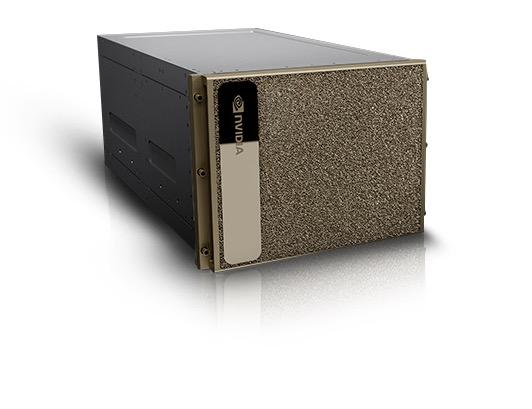
Integrated Enterprise Node
NVIDIA DGX SystemsThe Industry Standard
NVIDIA DGX H100 / DGX SuperPOD System
The undisputed industry standard for accelerated computing and frontier deep learning, serving as the blueprint for DGX SuperPODs.
Accelerators
8x NVIDIA H100
SXM5 Baseboard
Total HBM
640 GB
26.8 BW
FP8 Compute
32 PFLOPS
FP8 (Sparse)
REAL-LIFE AI TRAININGPre-Training
175B Parameter Transformer (GPT-3 Class): An 8-node DGX SuperPOD cluster (64 GPUs) trains a 175B parameter foundation model across billions of tokens using 3D Megatron parallelism.
Throughput:Over 18,500 tokens/sec across FP8 Transformer Engine optimization
Host CPUs:Dual Intel Xeon Platinum 8480C Processors
System RAM:2TB DDR5
GPU Fabric:NVIDIA NVLink 4 (900 GB/s bidirectional per GPU)
Cooling & Power:High-Capacity Air • 10.2 kW max system power
Architecture Type
Turnkey Enterprise Node
5U High-Density Rackmount
💨 High-Capacity Air
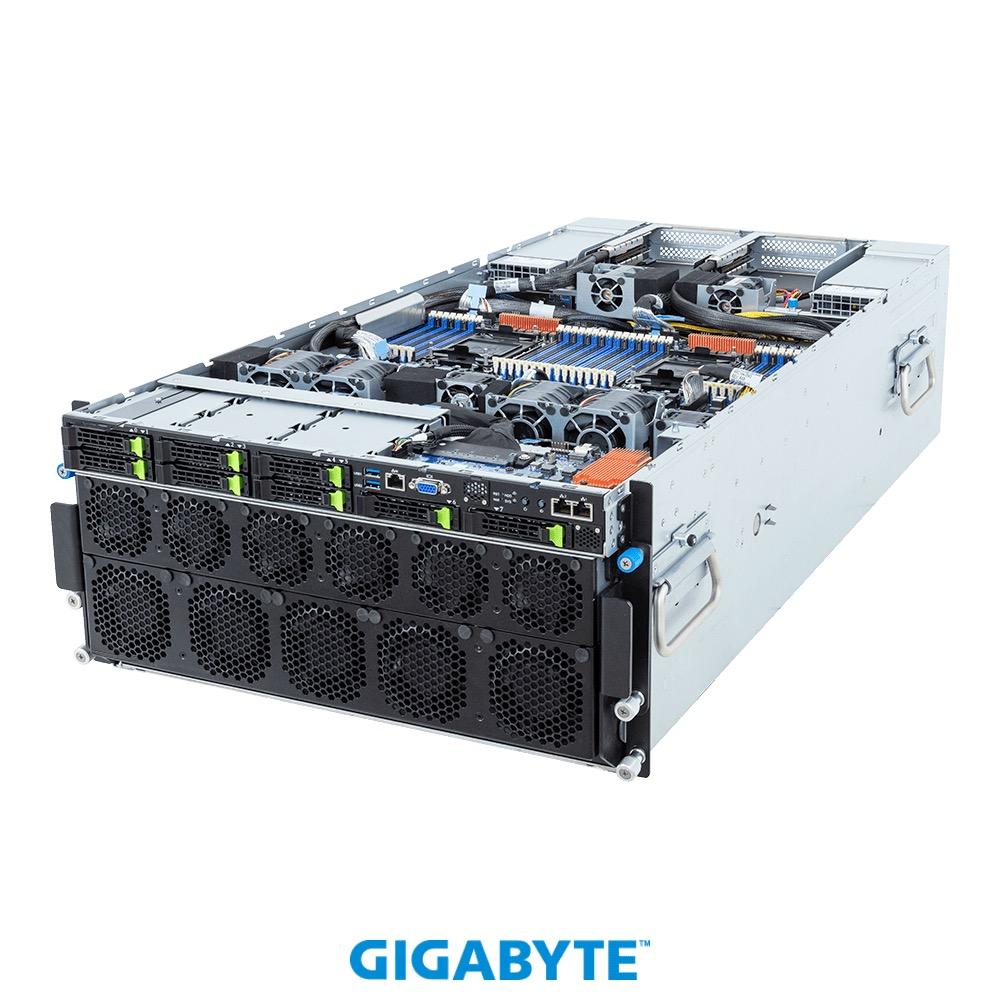
Integrated Enterprise Node
Gigabyte HGX (H100 / B200)5U Ultra-Dense Frontier Node
Gigabyte G593-SD0 / XL43 HGX Training Server
Widely used frontier training nodes for heavy enterprise workloads, packing 8x SXM accelerators into an industry-leading 5U form factor.
Accelerators
8x NVIDIA H100
SXM5 Baseboard
Total HBM
640 GB
26.8 BW
FP8 Compute
32 PFLOPS
FP8 (Sparse)
REAL-LIFE AI TRAININGPre-Training
DiT (Diffusion Transformer, 14B Video Model): Trains continuous high-resolution 1080p latent video generation models requiring massive continuous FP8 tensor contractions.
Throughput:3x faster frame generation training than prior generation
Host CPUs:Dual 5th Gen Intel Xeon Scalable Processors
System RAM:Up to 2TB DDR5-5600 MT/s ECC Registered
GPU Fabric:900 GB/s NVLink 4 bidirectional (upgradable to 1.8 TB/s NVLink 5 B200)
Cooling & Power:High-Capacity Air • 10.0 kW to 12.5 kW peak power
Architecture Type
Turnkey Enterprise Node
8U OAM High-Density Server
💨 High-Capacity Air
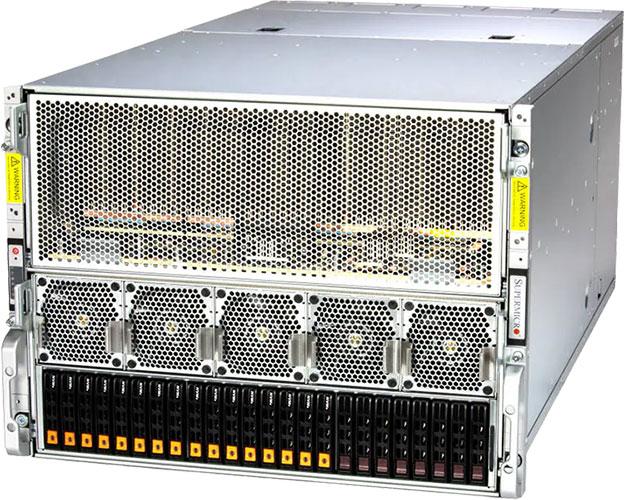
Integrated Enterprise Node
AMD EPYC GPU Servers1,536 GB HBM3 Memory Monster
AMD EPYC Instinct MI300X 8-GPU Enterprise Server
Memory-rich alternative systems powered by AMD Instinct MI300X accelerators and dual AMD EPYC processors, providing 1.54 TB of high-speed HBM3.
Accelerators
8x AMD MI300X
OAM Platform
Total HBM
1,536 GB
42.4 BW
FP8 Compute
20.8 PFLOPS
Matrix Cores
REAL-LIFE AI TRAININGFine-Tuning
Llama 3.1 70B Base: With 1,536 GB total VRAM, all FP16 model weights, gradients, and AdamW optimizer states fit on a single node without CPU offload or tensor parallelism across the network.
Throughput:Eliminates network communication latency entirely
Host CPUs:Dual AMD EPYC 9004 / 9654 Genoa Processors
System RAM:Up to 3TB DDR5-4800 / 5600 MT/s ECC Registered RDIMMs
GPU Fabric:AMD Infinity Fabric 8-way all-to-all mesh (896 GB/s bidirectional per GPU)
Cooling & Power:High-Capacity Air • 10.5 kW peak power
Architecture Type
Turnkey Enterprise Node
VERIFIED CUSTOM PC BUILDS & TEMPLATES
Production-tested consumer configurations with verified 2D/3D component clearances, calibrated power transients, and benchmark curves.
ULTRA ENTHUSIASTSCORE: 99/100
Intel + NVIDIA Ultimate Rig
Zero-compromise 4K ray tracing and high-bandwidth workstation compute.
•Intel Core Ultra 9 285K • 24 Cores / 5.7 GHz
•NVIDIA GeForce RTX 5090 • 32GB GDDR7
•Seasonic Prime 1300W ATX 3.1 80+ Titanium
•Crucial T705 4TB PCIe 5.0 (14.5 GB/s)
Total Build
$6,850
CYBERPUNK NEONSCORE: 95/100
AMD Ryzen Aesthetic Cyberpunk Build
Peak gaming FPS with 3D V-Cache and synchronized neon ARGB chassis.
•AMD Ryzen 7 9800X3D • 96MB 2nd Gen 3D V-Cache
•NVIDIA GeForce RTX 5080 • 16GB GDDR7
•ASUS ROG Crosshair X870E Hero
•Lian Li O11 Dynamic EVO RGB Dual-Glass
Total Build
$3,490
VALUE CHAMPIONSCORE: 84/100
Budget 1440p High-CFM Air Cooled Rig
Maximum price-to-performance ratio with zero pump failure risk.
•AMD Ryzen 7 9700X • 65W High-Efficiency Zen 5
•Intel Arc B580 • 12GB GDDR6 Xe2 Architecture
•Thermalright Peerless Assassin 120 SE Dual Tower
•Corsair 4000D Airflow High-CFM Mesh Chassis
Total Build
$1,380